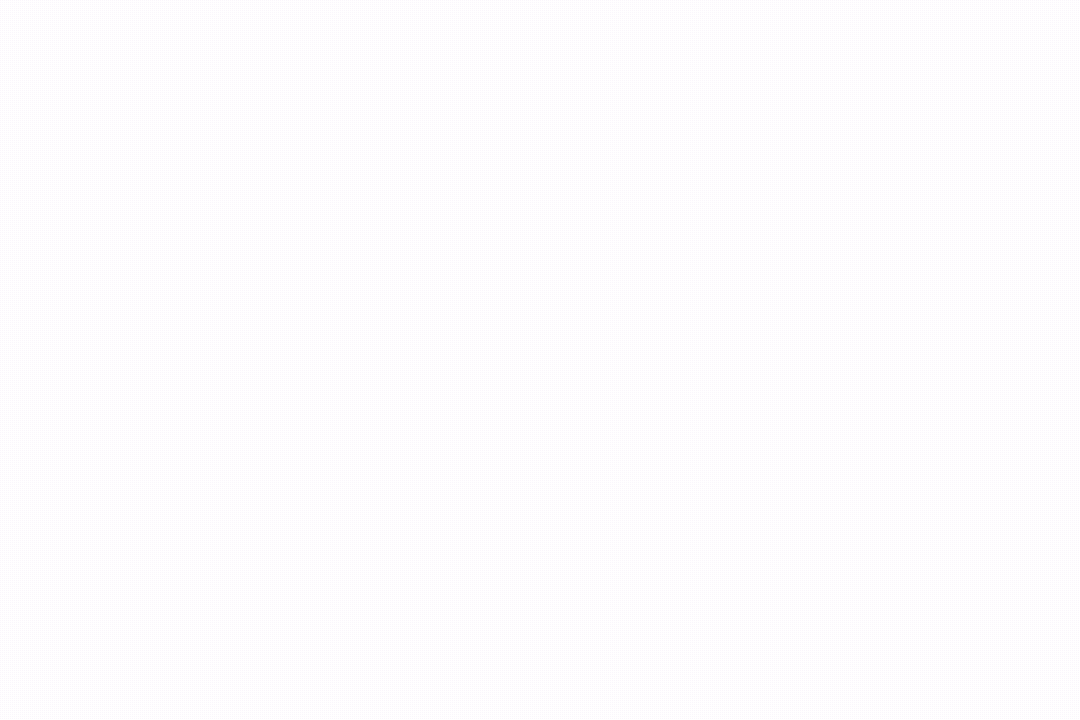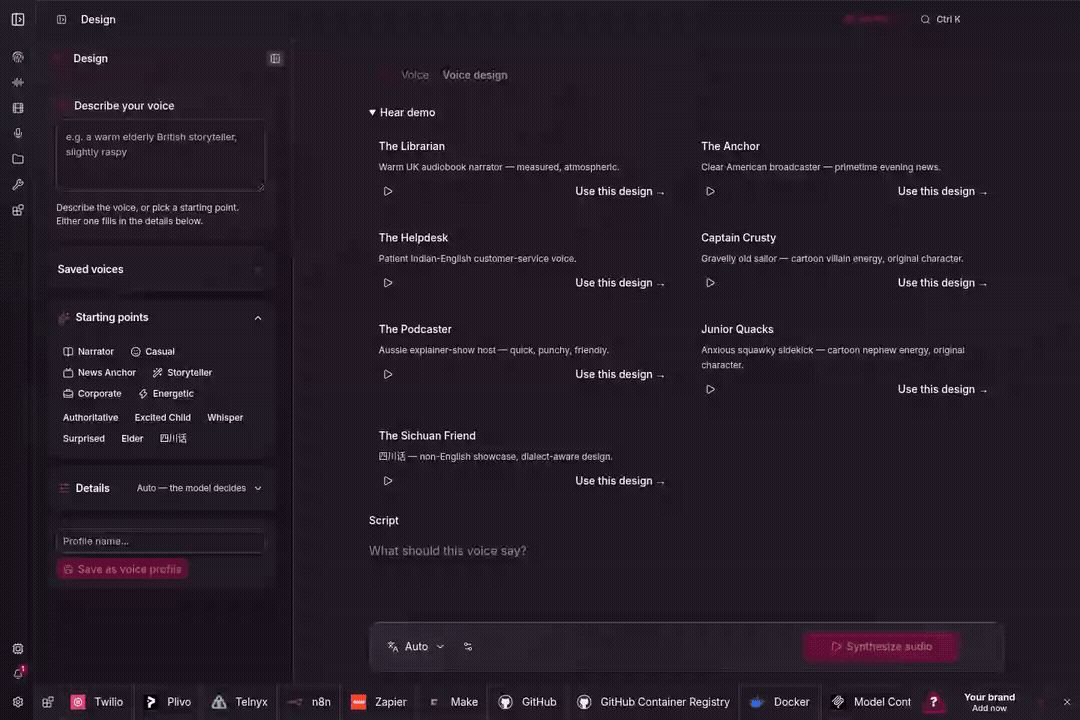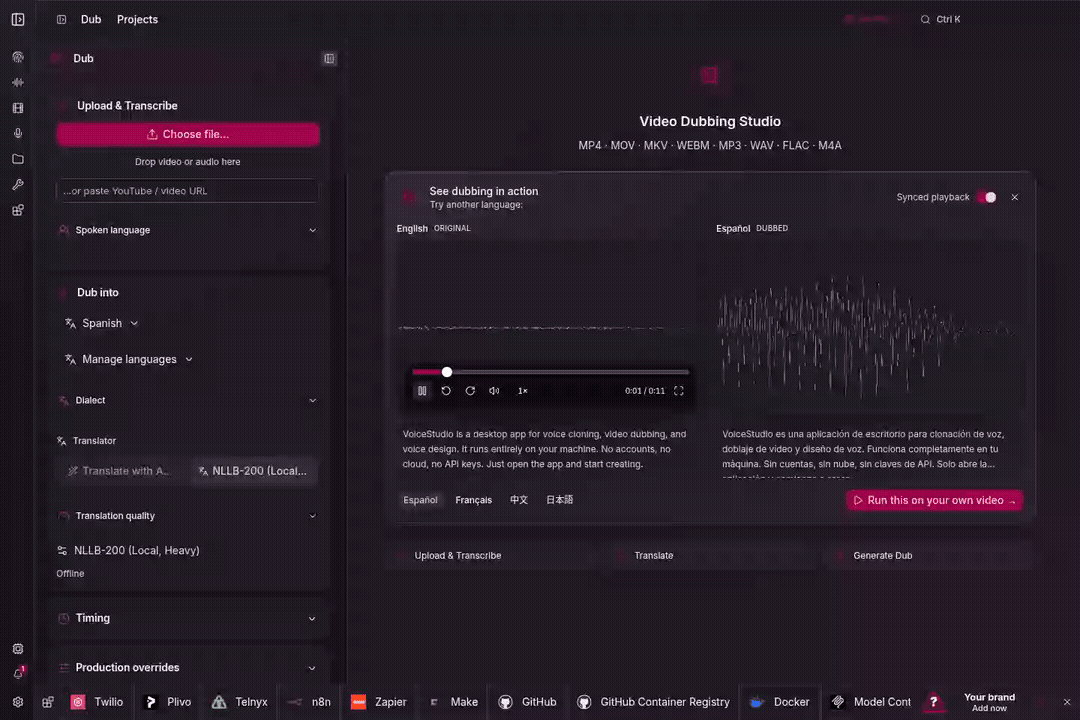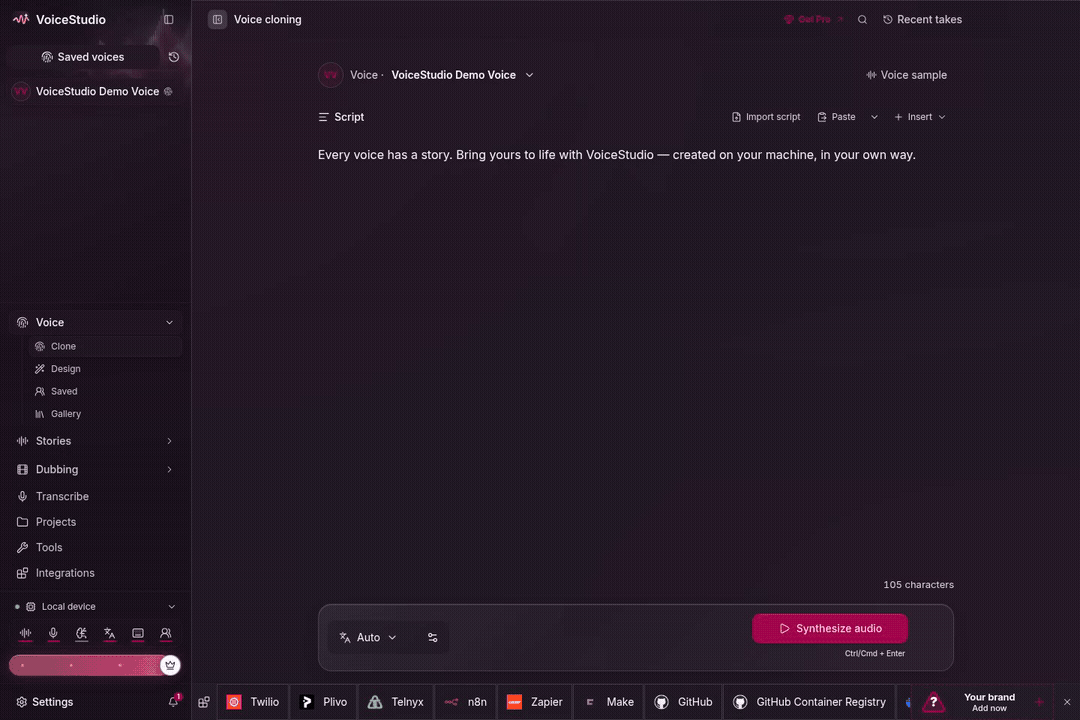
1. Why VoiceStudio Smashed Records in 24 Hours
The meteoric rise of VoiceStudio isn't just hype; it addresses a critical market gap: the demand for privacy-first, zero-cost-per-token voice synthesis. By bringing the entire ElevenLabs pipeline (cloning, dubbing, transcription) to the edge, it enables developers to bypass API costs and data privacy constraints entirely.
2. Architectural Deep Dive
VoiceStudio isn't merely a wrapper; it's a sophisticated pipeline orchestration system: - Inference Engine: Built on optimized VITS/RVC variants, specifically quantized for multi-language phoneme alignment. - Transcription Layer: Employs a distilled version of Whisper-large-v3, optimized for high-throughput, low-latency edge processing. - Modular Weight Management: Decouples model weights from the runtime logic, allowing for hot-swapping voice models without restarting the server.
| Feature | ElevenLabs (API) | VoiceStudio (Local) |
|---|---|---|
| Data Privacy | Cloud-side | Full Local Residency |
| Cost | Usage-based | Hardware-only |
| Latency | Network-dependent | VRAM-throughput dependent |
| Customizability | Limited | Fully Extensible |
3. Practical Deployment Guide
Prerequisites
- VRAM: 8GB minimum; 12GB+ recommended (RTX 3060/4070).
- OS: Ubuntu 22.04 LTS or WSL2.
Rapid Deployment
# Clone the repository
git clone https://github.com/debpalash/VoiceStudio
cd VoiceStudio

# Install dependencies
pip install -r requirements.txt

# Launch the inference server
python app.py --model_path ./weights --gpu_id 0
Tuning for Production
Within config.yaml, optimize for long-form audio tasks:
- chunk_size: Set to 2048 to balance VRAM usage against throughput.
- sampling_rate: Set to 44100 for studio-grade output quality.
4. Engineering Trade-offs
Pros: - Zero API Dependency: Immune to API rate limits or sudden price hikes. - Modular Design: Easy to plug in custom-trained Lora models for unique voice identities.
Cons: - Cold Start: Initial model weight loading can be significant depending on storage speed. - Hardware Constraint: Requires dedicated GPU resources, making it unsuitable for low-power mobile or edge devices without offloading.